
Cohere’s October 6 announcement says Tiny Aya L2-Thinker reasons in the prompt language more than 93% of the time across 60 languages. The linked arXiv paper v1 was submitted September 9, 2026.
Two scores, different questions
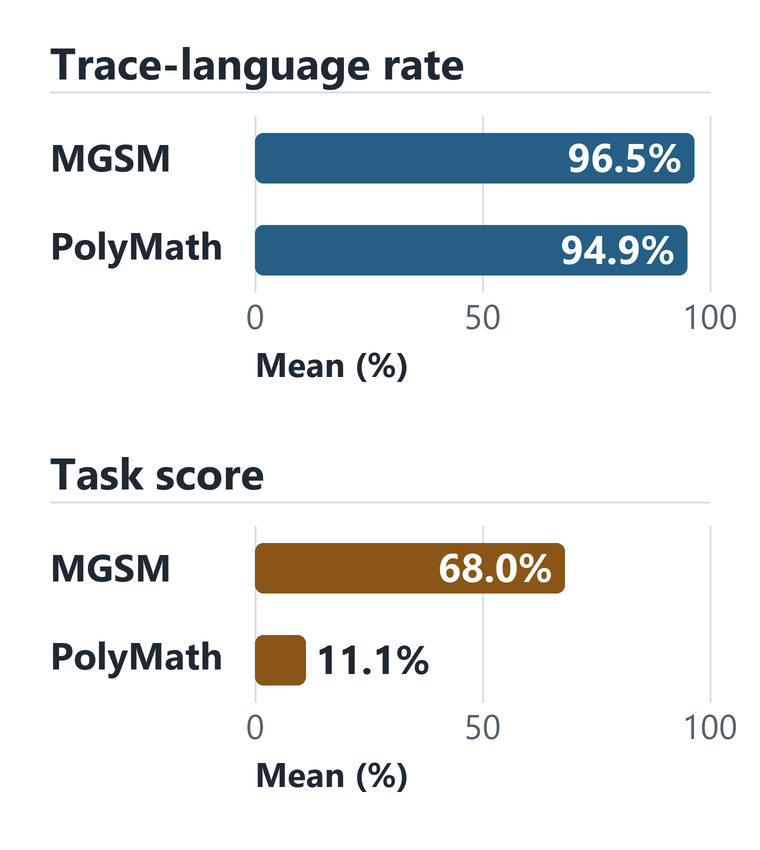
L2 rate means traces are mostly in the prompt language, not accurate answers. MGSM reports accuracy; PolyMath reports a weighted score. L2 rate uses FastText, falling back to GlotLID for unsupported languages.
| Benchmark (non-English languages) | Task score, mean ± SD (%) | L2 rate, mean ± SD (%) |
|---|---|---|
| MGSM (34) | 68.0 ± 14.1 | 96.5 ± 9.6 |
| PolyMath (17) | 11.1 ± 2.5 | 94.9 ± 7.7 |
Paper v1 names Tiny Aya L2-Thinker (3.35B); conditions: one completion per example, 32K context. Unreported: checkpoint hash, temperature, seed and inference hardware. Table 1 lacks sample-level denominators for its non-English means. The figures were not independently reproduced; no weights or dataset bytes were downloaded and no inference was run. Paper methods.
Proposed evaluation example (not run)
Prompt text: “¿Cuánto es 17 × 19?”; expected answer: “323.” For an actual response, record the trace-language classifier label, a separate human code-switch flag and the final-answer score. Flag a mixed trace for review even if the answer is correct; a trace that stays in Spanish still fails the task criterion if its answer is wrong. The paper gives no numeric cutoff for “predominantly”; preregister and report yours. No model response is supplied.
Log for each item: model/checkpoint hash; dataset commit, subset and split; prompt language; benchmark and scoring version; trace-classifier label; human code-switch flag; final answer and score; actual decoding settings. Keep automatic classification separate from human review, and never copy demo defaults into a paper reproduction.
Access and reproduction (checked October 6, 2026)
The model card describes a text-only checkpoint trained for reasoning in 44 non-English languages plus English. Model files require Hugging Face sign-in and acceptance of CC-BY-NC-4.0 conditions; Cohere Labs’ Acceptable Use Policy also applies. The card directs commercial users to Cohere sales. Its authored local-use instructions show a Transformers path.
The dataset card provides a public viewer for 44 non-English subsets and lists train/test splits, 1.24 GB and 286,376 rows. It names prompts from AM-DeepSeek-R1-0528-Distilled, traces and outputs from gpt-oss-120b, and translations using Command A Translate and DeepSeek-V3. The card marks the dataset CC-BY-NC-4.0.
Paper Table 3 lists 286,388; the difference is unexplained. Before reproducing, pin the dataset commit, configuration, subset and split, then record the observed row count.
Cohere’s current model list lists Tiny Aya Global, Earth, Fire and Water, but not L2-Thinker. Hugging Face shows no inference-provider deployment for this checkpoint. Cohere’s article links a Space demo, which was not tested. A public L2-Thinker API route is therefore unconfirmed; ask Cohere for the exact model ID if hosted inference is required.
For document extraction rather than multilingual reasoning, see our Cohere Parse API guide.