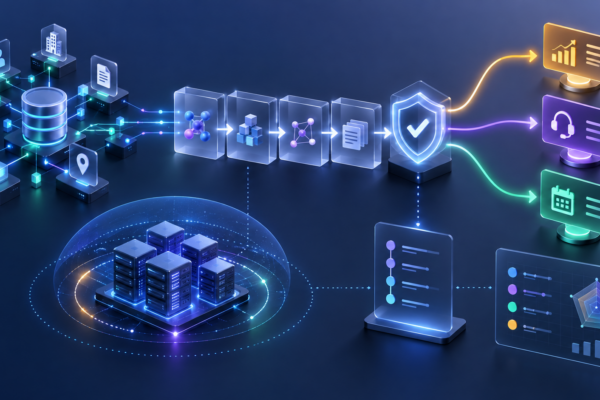

Short answer: Cohere Parse is the live parse-v5.0 vision-language model for turning enterprise document images into machine-readable Markdown or ordered content blocks. Cohere documents a 2.3B-parameter model with an 8,192-token context, text and visual extraction, tables, lists, forms, images, captions, page boundaries and visual-element locations. It is available through the Parse API, Model Vault, Microsoft Foundry and AWS SageMaker, and is also part of Cohere’s Compass search stack.
The most important integration warning is easy to miss: Cohere’s model documentation lists PDF, PPT and JPEG as supported file types, but the current /v2/parse API reference says the request currently accepts document.type = "image_url" only and that PDF or file-URL inputs are not yet supported. The direct API publishes a 20 MB image limit and a 50-megapixel or 200 MB decoded limit, whichever is exceeded first. A PDF or slide workflow may therefore need an upstream render-to-image step, or a different deployment surface, until Cohere confirms a native file path.
Cohere’s launch page lists API pricing at $1.50 per 1,000 pages. The current Standard Model Vault price table lists Parse 5 at $4 per Medium instance-hour or $7 per XL instance-hour. Those are different billing units and access paths, not interchangeable quotes. Cohere reports strong ParseBench, throughput and cost comparisons, but they are vendor-reported; its detailed docs also say Parse does not return confidence scores, does not identify headers or footers, and does not support arbitrary structured JSON output.
| Buyer question | Current evidence | What remains to verify |
|---|---|---|
| What is Parse? | Live Cohere vision-language document parser, model ID parse-v5.0. | Model-version pinning and behaviour in the chosen API/cloud deployment. |
| What does it return? | Markdown by default or ordered blocks; tables can be HTML, images have descriptions and locations. | Whether the output preserves the fields and formatting your downstream schema requires. |
| Can I send a PDF directly? | Model docs list PDF/PPT/JPEG; current v2 reference accepts image URLs/data URIs only and excludes PDF/file URLs. | Render-to-image pipeline or platform-specific file support. |
| Does it understand handwriting? | Cohere’s product overview uses a handwriting claim; detailed Parse docs do not list handwriting or publish a handwriting score. | Test handwriting separately; do not promise it from the overview badge. |
| What does it cost? | $1.50/1,000 pages via the launch API claim; Model Vault Parse 5 is $4 Medium or $7 XL per instance-hour. | Current account, region, cloud-provider, Vault tier, commitment and total-cost terms. |
What Cohere Parse is—and what it is not
Cohere announced Parse on August 27, 2026 as a high-throughput document-intelligence model. It is designed to reduce complex documents to content that search, retrieval-augmented generation (RAG) and agent workflows can consume. Cohere positions it as “beyond OCR”: the model is intended to preserve reading order and understand tables, forms, diagrams and embedded images rather than returning only a flat string of characters.
The current model documentation is narrower and more actionable. It describes a proprietary north-micro-vision-instruct architecture, approximately 4.6 GB in model size, an 8,192-token context and Markdown output. It lists text and reading order, tables, lists, forms and key-value pairs, images and captions, page boundaries and visual-element locations. The model overview marks parse-v5.0 Live and maps it to the Parse endpoint; the same page maps it to a unique SageMaker deployment name and cohere-parse-v5.0 on Azure AI Foundry.
That makes Parse a document parser, not a general-purpose chat model or a complete document-management system. It does not replace chunking, indexing, access control, citation, schema validation, human review or the business application that acts on extracted data. Cohere’s Compass product can combine Parse with Embed and Rerank, but the model and the broader managed search product should remain separate line items in an architecture and a quote.
Access paths and deployment choices
| Path | What Cohere documents | Best first use | Important boundary |
|---|---|---|---|
| Cohere Parse API | POST /v2/parse, model parse-v5.0, image URL/data URI, Markdown or blocks. | Small, non-sensitive prototype or controlled page-level ingestion. | Current reference is image-only; 20 MB and pixel/decoded-size limits apply. |
| Model Vault | Cohere-managed, single-tenant Parse 5 inference; Standard or Encrypted Vault. | Commercial sustained workloads needing dedicated serving and monitoring. | Per-instance-hour pricing, tier/replica/region and contract terms require confirmation. |
| Microsoft Foundry | Azure endpoint example with cohere-parse-v5.0 and the Cohere SDK. | Teams already governed by an Azure model endpoint. | Azure subscription, endpoint region, payload and provider terms apply. |
| AWS SageMaker | Cohere announces general availability and the model overview maps SageMaker to a unique deployment name. | AWS-managed deployment and account-native operations. | Exact region, image/file contract, price and deployment identifier are account/provider-specific. |
| Compass | Parse can sit alongside Embed and Rerank in Cohere’s search and retrieval stack. | Managed document ingestion-to-retrieval workflows. | Compass packaging, connectors, indexes and document permissions are not the same as the standalone Parse API. |
The launch page also says Parse is available in a free Hugging Face Space for trying documents. That demo is useful for discovery, but it does not establish API quotas, enterprise retention, production support or a self-hosted weight download. Parse’s model documentation calls the architecture proprietary; this is not an open-weight release like some other Cohere Labs models.
The direct API contract is narrower than the file-type summary
Cohere’s details page says Parse supports PDF, PPT and JPEG (Base64 encoded). Its quickstart speaks about PDFs, images and slides. The current v2 API reference, however, defines the request document as an image_url and explicitly says PDF and file-URL inputs are not yet supported. The accepted image URL can be a remote HTTP(S) URL or a data URI. This is a documentation boundary, not a cosmetic wording difference.
For a PDF or PowerPoint pipeline, the safe design is to make conversion visible:
- Keep the original file and page identifier.
- Render each page to an approved image format at a resolution that preserves small text and table lines.
- Validate the encoded image before sending it: the direct API reference publishes a 20 MB file limit and a 50-megapixel or 200 MB decoded limit.
- Call Parse with the exact model ID and requested output format.
- Store the page index, raw response, output hash and any conversion warnings.
Cohere’s best-practices page recommends WebP at quality 90 for general parsing and PNG or JPEG at quality 95 for tables and high-precision documents, with a 2,048-pixel long side as a practical image size. This is guidance, not a universal guarantee; a small-font financial table may need a targeted resolution test. The docs do not publish a maximum page count per logical document in the current reference. Billing and response objects are page-oriented, so measure pages and conversion work explicitly.
Output formats: Markdown or typed blocks, not arbitrary JSON
Parse defaults to Markdown. The response is page-oriented and can include document text, lists, HTML-formatted tables, image references, image descriptions and bounding boxes where available. This is useful when the next step is rendering, chunking or indexing a document while retaining some structure.
The API also supports output_format="blocks". In that shape, each page includes an ordered array of text, image and table regions, with type-specific fields and bounding boxes where available. That is a structured response envelope, but it is not a user-defined JSON schema extractor. Cohere’s model details explicitly say structured JSON output is not supported.
That distinction matters for invoices, claims or contracts. If the downstream system requires a strict object such as {"invoice_number": ..., "total": ...}, use Parse to preserve the page and table evidence, then add a separately validated extraction step. Do not silently treat a Markdown table as a trustworthy accounting record. Validate required fields, units, currency, totals, page provenance and conflicting values before any write or payment decision.
Parse also does not return confidence scores for extracted content. Add your own validation signals: field presence, arithmetic checks, expected table shape, duplicate detection, source-page links, human sampling and escalation. The absence of a model confidence field is a product boundary, not evidence that every output is equally reliable.
OCR, tables, forms, images, diagrams and handwriting
Parse’s documented extraction scope goes beyond character recognition:
- Text and reading order: useful for turning multi-column pages into a sequence for search or RAG.
- Tables: returned as HTML inside Markdown or as table blocks, with bounding boxes where available.
- Lists and forms: the model docs include lists and key-value pairs as supported extraction targets.
- Images and captions: images can be referenced with descriptions and locations rather than discarded as noise.
- Page boundaries and visual locations: useful for provenance, rendering and retrieval links.
The launch article also says Parse understands diagrams and returns spatial information. Keep that claim scoped. The detailed documentation does not promise numeric chart extraction, arbitrary visual-grounding labels or a full page-layout tree. Cohere’s own ParseBench footnote says Layout and Chart dimensions were excluded because they are outside the current product scope: Parse produces reading-order Markdown and does not emit per-element text bounding boxes, while chart data extraction is planned for a future Parser version.
Handwriting needs an especially careful label. Cohere’s current enterprise-model overview describes Parse 5 as understanding tables, forms and handwriting. The detailed Parse page lists nine stable input languages and the extraction targets above, but does not list handwriting or publish a handwriting benchmark. Treat handwriting as a marketing-page claim to validate on representative samples, not as a guaranteed capability. Test cursive, low contrast, annotations, mixed printed/handwritten forms and the consequences of a missed field separately.
Language scope and OCR boundaries
Cohere documents stable Parse input support for nine languages:
| ISO code | Language |
|---|---|
| ar | Arabic |
| en | English |
| fr | French |
| de | German |
| ja | Japanese |
| ko | Korean |
| it | Italian |
| pt | Portuguese |
| es | Spanish |
The same page says zero-shot parsing of additional languages is possible, but accuracy may be lower than for the recommended set. Do not turn a multilingual interface or an OCR-capable vision model into a universal language guarantee. Include the exact scripts, markets and document layouts in your first test set, especially for Japanese, Korean, Arabic and mixed-script documents.
For non-Latin text, image quality and font size matter. Cohere’s image-input guidance advises enlarging small text when possible and notes that performance may vary for non-Latin alphabets. A document that looks legible at full resolution may still become a poor input after compression, rendering or a data-URI transformation. Preserve the pre-processing parameters in the evaluation receipt.
Context, file and request limits
| Limit or control | Current documentation | Operational implication |
|---|---|---|
| Model context | 8,192 tokens. | Do not assume a whole long document can be handled as one prompt; parse page-by-page and preserve provenance. |
| Direct request type | document.type="image_url" only in the current v2 reference. | Use a remote image URL or data URI; render PDFs/slides upstream unless another channel confirms native support. |
| Image file size | 20 MB. | Validate before upload and account for Base64 expansion in transport. |
| Decoded image size | 50 megapixels or 200 MB decoded, whichever is exceeded first. | Resize or split oversized scans; keep the original for audit. |
| Output | Markdown or blocks; page-oriented response. | Build downstream schema validation; arbitrary JSON and confidence scores are not provided. |
| Parse rate limit | Cohere’s rate-limit table lists 500 requests/minute for trial and production keys. | Measure pages per request and implement retry/backoff; do not equate request rate with page throughput. |
| Maximum page count | No explicit maximum page count was found in the reviewed API reference. | Ask Cohere or test the chosen deployment; do not infer an unlimited document size. |
The API reference lists normal error responses, including 400, 401, 403, 404, 422, 429, 498, 499, 500, 501, 503 and 504. A production queue should classify authentication, payload, size, rate, transient and unsupported-file errors separately. Retrying a PDF payload rejected because the endpoint is image-only will not fix the contract.
Pricing and billing units
Cohere’s Parse launch page states a Cohere API price of $1.50 per 1,000 pages. That is a page-based public launch price and should be checked against the live account before budgeting. The current rate-limit documentation lists Parse at 500 requests per minute for both trial and production keys. Cohere’s pricing FAQ says trial API calls are free but trial keys are rate-limited and not permitted for production or commercial purposes; production-key calls are pay-as-you-go.
For Model Vault, Cohere’s current Standard pricing table lists:
| Model Vault item | Performance tier | Hourly rate per instance | Monthly rate per instance |
|---|---|---|---|
| Parse 5 | Medium | $4.00 | $2,500 |
| Parse 5 | XL | $7.00 | $4,300 |
Model Vault pricing is per instance and performance tier, with fixed or flex plans and possible autoscaling. The published table is not a per-page price. Compare it with API page billing only after adding replica minimums, uptime, page volume, preprocessing, storage, networking, indexing, human review and the support/SLA terms. Encrypted Vault pricing is separate.
Cohere’s launch page gives a worked high-volume scenario: at roughly 13 million pages per month, it says Model Vault could save about $12,000 per month versus the API and about $1.47 million annually versus a hyperscaler priced at $10 per 1,000 pages. It also reports 23% lower inference cost at 50% GPU utilization and up to 61% at full hourly utilization. These are Cohere’s assumptions and calculations, not an independent quote or a forecast for your workload. Recalculate with your actual pages, retries, quality review, storage, region and contract. DMT’s model API pricing checklist is an adjacent reminder to record the exact endpoint, billing unit and limits before comparing providers.
Privacy, retention and deployment security
Parse’s data boundary follows the deployment path. Cohere’s Enterprise Data Commitments say private and third-party deployments do not expose customer prompts or generations to Cohere. The same commitments describe SaaS logging and retention controls, training opt-out and a general 30-day deletion period for logged prompts and generations, subject to agreements, legal requirements and flagged-use exceptions. Cohere’s Privacy Policy says trial and research users should not use the platform for personal information and directs enterprise users toward commercial terms and a data-processing addendum where appropriate.
Standard Model Vault is a Cohere-managed, logically isolated, single-tenant environment with data protected in transit and at rest. Cohere says that when Zero Data Retention is enabled for a Standard Vault standalone deployment, it processes inputs and outputs without retaining prompts or responses. Encrypted Vault adds hardware-backed protection in use and remote attestation. These are documented controls, not a substitute for checking the selected region, model availability, retention setting, key management, support plan and customer agreement.
For regulated document workflows, ask four separate questions:
- Where is the original file, rendered page image, Parse request, response and downstream index stored?
- Who can view the raw document, extracted text, image descriptions, bounding boxes and logs?
- Is training opt-out, ZDR or encrypted processing actually enabled for this account and route?
- What happens when parsing fails, a field is missing, or a page contains personal or privileged information?
Do not describe a $1.50 page API call as private by default, and do not describe a Standard Vault as hardware-attested. Match the privacy sentence to the specific deployment and contract.
How Cohere evaluated Parse
Cohere reports a ParseBench three-dimension average of 79.2 for Parse. Its table reports 87.0 for Tables, 86.6 for Content Faithfulness and 64.0 for Semantic Formatting. Cohere compares those scores with Mistral OCR 4, Databricks AI Parse, LlamaParse, Azure Document Intelligence, Google Document AI, AWS Textract and other systems, and says the model is surpassed by larger frontier LLMs in its evaluation set.
Cohere defines the dimensions as follows:
- Tables: structural extraction of data grids and cells.
- Content Faithfulness: omissions, hallucinations and broken reading order.
- Semantic Formatting: styles that change meaning, such as strike-through or italics.
The launch footnote says the reported scores use the latest rules as of August 2026, including a fix to bold and heading detection, and that competitors were re-scored under the updated rules. Cohere explicitly excludes Layout and Chart dimensions because it considers them outside the current product scope. That means a lower score on those dimensions would not necessarily be a product defect under Cohere’s definition, but it also means ParseBench does not answer every document-intelligence question.
The benchmark page does not publish a complete public task count, domain mix, document-length distribution, annotation agreement, confidence interval or raw output set in the launch article. Treat the comparison as a Cohere evaluation, not independent proof. A ParseBench lead over a competitor may not survive your scanned forms, handwritten notes, charts, languages, resolution or downstream schema.
Cohere also reports 4.5 pages per second for Parse, or 36 pages per second on an 8-H100 node, and compares it with open-source models served using vLLM under a consistent setup. That is a useful hardware-specific throughput signal. It is not an end-to-end latency SLA: rendering, upload, queueing, response transfer, retries, indexing and human review are outside the number.
Integration fit: Parse, Embed, Rerank and Compass
Parse’s most defensible integration role is the first stage of a document-to-search pipeline. For the downstream agent and document-automation context, see DMT’s documents and multi-agent builds guide; it remains a separate model and application owner.
- Ingest: collect the original file, permission metadata and page identifiers.
- Render or submit: use the correct Parse surface and validate the current file contract.
- Parse: store Markdown or blocks, images, tables, descriptions and available locations.
- Validate: check required fields, page count, table totals, language and output markers.
- Chunk and index: use a deliberate chunking strategy and preserve page citations.
- Embed and rerank: add Cohere Embed and Rerank, or use Compass if its managed connectors and access controls fit.
- Answer or act: let an agent use the parsed context only after access, citation and approval controls are tested.
Parse does not make a retrieval system trustworthy by itself. A perfect table transcription can still be indexed under the wrong tenant, retrieved without document-level permissions or used to answer a question from a stale version. A failed image parse can silently remove the clause a downstream agent needed. Keep source-page references and parse failures visible to the retrieval and application layers.
DMT’s VLM Run OCR and visual-AI workflow guide is the closest existing visual/OCR owner for comparison. It covers a different product and workflow; this page owns Cohere Parse’s current API contract, document limits, output shape, pricing and deployment boundaries.
A safe first pilot
- Choose one document family. Start with invoices, support manuals, policies or product sheets, not every file in the repository.
- Freeze the input route. Record whether the test uses direct images, rendered PDFs, Foundry, SageMaker or Model Vault. Capture resolution, format, compression and page count.
- Build a gold set. Have a human mark reading order, tables, key-value fields, images, omissions, additions, formatting and citations. Include failure cases and sensitive content only under an approved data path.
- Compare an incumbent. Run the existing OCR/parser and Parse under equivalent inputs. Track field accuracy, table structure, source-page alignment and human correction time.
- Validate the output contract. Reject missing totals, malformed tables, broken markup, wrong page boundaries, unlabelled images and unsupported JSON assumptions before indexing.
- Measure operating cost. Count rendered pages, API requests, billed pages, retries, rate-limit events, GPU hours, Vault replicas, storage, embedding/reranking and human review.
- Test the hard edges. Include small text, multi-column pages, charts, diagrams, handwriting, mixed scripts, skew, low contrast, tables spanning pages and documents near the 20 MB/50 MP/200 MB limits.
- Gate automation. Keep the first release read-only. Add one reversible downstream action only after parse quality, permissions, provenance, retention and rollback are approved.
This is an evaluation recommendation, not a Cohere product requirement. The code examples in Cohere’s quickstart and API reference were source-checked but not executed here because no authorised API key or customer document set was available.
Verified facts, vendor claims and unknowns
| Evidence class | Current statement |
|---|---|
| Verified in current Cohere docs | parse-v5.0 is Live; 2.3B parameters; about 4.6 GB; 8,192 context; PDF/PPT/JPEG listed at the model-doc level; nine stable input languages; Markdown output; blocks or Markdown at the API level. |
| Verified in current API reference | POST /v2/parse accepts image URLs/data URIs only; PDF/file URLs are not yet supported; image size is capped at 20 MB and 50 MP or 200 MB decoded; output can be Markdown or blocks. |
| Vendor launch claim | $1.50 per 1,000 pages, ParseBench 79.2, 4.5 pages/second, Model Vault savings and handwriting/diagram/visual-understanding positioning. |
| Not established | Maximum page count, pairwise language quality, handwriting accuracy, chart extraction, confidence scores, arbitrary JSON schemas, universal regions, exact cloud-provider prices, independent quality or production outcomes. |
Frequently asked questions
Is Cohere Parse just OCR?
No. Cohere positions it as a vision-language parser that preserves reading order and extracts tables, lists, forms, images, captions and visual locations. It is still not a complete layout or chart-understanding system: the detailed docs omit headers, footers and font hierarchy, and Cohere’s benchmark footnote excludes Layout and Chart dimensions.
Can the Cohere Parse API accept a PDF directly?
The current v2 API reference says no: it accepts an image_url document, using a data URI or remote HTTP(S) image URL, and says PDF/file URLs are not yet supported. The broader model page lists PDF and PPT, so confirm the selected deployment surface or render pages to images before building against the direct API.
Does Parse return JSON?
It returns Markdown by default or ordered blocks. Tables can be represented as HTML and blocks carry typed content and locations where available. Cohere’s detailed model page explicitly says arbitrary structured JSON output is not supported, so add a separately validated extraction step when your application needs a strict schema.
Does Parse read handwriting?
Cohere’s enterprise-model overview mentions handwriting, but the detailed Parse documentation does not list handwriting among its documented extraction targets or publish a handwriting score. Treat it as an unverified product claim and test representative handwriting before promising it to a customer or regulated workflow.
How much does Parse cost?
Cohere’s launch page states $1.50 per 1,000 pages through the API. The current Standard Model Vault table lists Parse 5 at $4 per Medium instance-hour or $7 per XL instance-hour. Confirm the live account, region, commitment, provider billing and other pipeline costs before comparing them.
Is Parse available in every region?
The reviewed sources list the Cohere API, Model Vault, Microsoft Foundry and AWS SageMaker, but do not provide one complete region-by-file-type-by-tier matrix. Confirm the endpoint, region, model availability, data residency and provider terms for the intended deployment.
Bottom line
Cohere Parse is a credible document-intelligence release for teams that need page-oriented Markdown or blocks from visual documents and want a direct path into search, RAG or agent context. Its strongest documented fit is high-volume text, table, form and image parsing under a controlled pipeline. The current API price is easy to understand, and Model Vault gives enterprises a separate dedicated-serving option.
The implementation catch is equally clear: the direct v2 contract is currently image-only even though the model page lists PDF and PPT, output is not arbitrary JSON, confidence scores are absent, handwriting and chart claims need testing, and vendor benchmark/throughput/savings figures are not independent guarantees. Start with rendered pages, a gold set, page-level provenance and human review. Choose API, Foundry, SageMaker, Standard Vault or Encrypted Vault only after the exact file contract, region, privacy terms, rate, billing unit and downstream validation path are written down.
Sources checked
- Cohere: Introducing Parse: Enterprise document intelligence at scale, August 27, 2026.
- Cohere Parse details and application, for model specification, extraction scope, languages and limitations.
- Cohere Parse v2 API reference, for
/v2/parse, image-only input, size limits and Markdown/blocks output. - Cohere Document Parsing quickstart and Parse best practices, for SDK patterns and image preparation.
- Cohere model overview and Parse release note, for Live status and Foundry/SageMaker/Model Vault mappings.
- Cohere API keys and rate limits, for the current Parse request-rate listing.
- Cohere pricing and Standard Model Vault pricing, for API/account and per-instance commercial context.
- Standard Vault overview, Encrypted Vault security model and Cohere on Microsoft Azure, for deployment and privacy context.
- Cohere Enterprise Data Commitments and Cohere Privacy Policy, for SaaS/private-deployment retention and data handling.
Scope note: This article reports Cohere, Cohere documentation, Model Vault, Microsoft Foundry, AWS/SageMaker mapping and current API-reference pages accessed on September 16, 2026. It preserves the PDF/PPT model-doc versus image-only API distinction, attributes ParseBench/throughput/cost/handwriting claims, and does not claim arbitrary JSON, confidence scores, handwriting accuracy, chart extraction, universal file support, complete regional availability, independent performance or a production SLA. No API key, customer document, cloud deployment or billing account was used.