TensorRT Multi-GPU in Dynamo-Triton 26.07: Config and Benchmark Interpretation
Configure a precompiled distributed TensorRT plan in Dynamo-Triton 26.07, then read NVIDIA's latency results without mistaking them for throughput or cost.
Configure a precompiled distributed TensorRT plan in Dynamo-Triton 26.07, then read NVIDIA's latency results without mistaking them for throughput or cost.
See Qwen-Image-2.1's RGBA workflow and local setup, then separate its research-only weight license from unresolved commercial-output and hosted API questions.
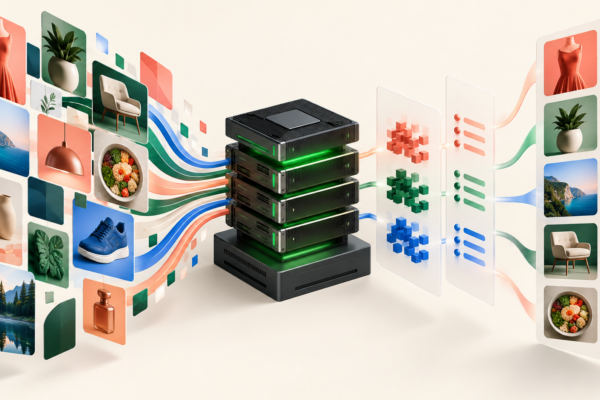
Pinterest’s NVIDIA multimodal AI foundation explained: Blackwell, Dynamo, visual embeddings, product scope, vendor metrics and advertiser limits.
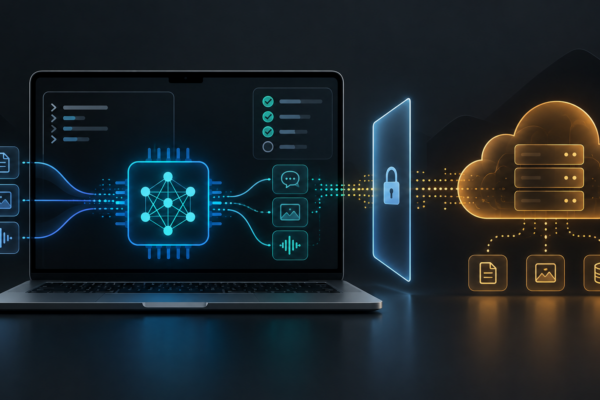
Apple Foundation Models on macOS 27 explained: local model access, fm CLI, Python SDK, Apple silicon requirements, PCC limits and evaluation steps.
Qwen3.8-Flash-Next is an experimental open-weight preview. See what marketers should test locally, when hosted Qwen3.8-Flash fits better, and what needs proof.

A working AI agent cost-per-accepted-result calculator with current GPT-5.6 price presets, tool costs, reviewer time, acceptance rate and an evaluation template.