TensorRT Multi-GPU in Dynamo-Triton 26.07: Config and Benchmark Interpretation
Configure a precompiled distributed TensorRT plan in Dynamo-Triton 26.07, then read NVIDIA's latency results without mistaking them for throughput or cost.
Configure a precompiled distributed TensorRT plan in Dynamo-Triton 26.07, then read NVIDIA's latency results without mistaking them for throughput or cost.
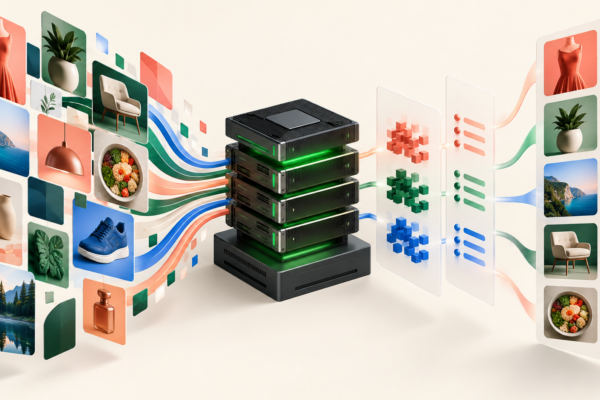
Pinterest’s NVIDIA multimodal AI foundation explained: Blackwell, Dynamo, visual embeddings, product scope, vendor metrics and advertiser limits.
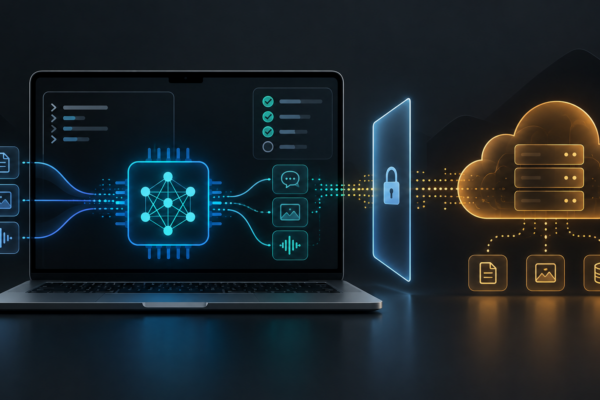
Apple Foundation Models on macOS 27 explained: local model access, fm CLI, Python SDK, Apple silicon requirements, PCC limits and evaluation steps.
Compare llama.cpp, PyTLLM, Swap-MoE, MLX-LM and bitsandbytes for local LLMs on limited VRAM or RAM, with safe settings and honest benchmarks.